A phone that predicts our next word and a chatbot that answers a question both rely on computers working with everyday communication. Natural language processing (NLP) helps software sort, interpret, and create messages people can use. But a fluent answer can still be wrong.
That gap matters when a user needs help, a customer asks for support, or a team must review a large set of messages. We can use these systems to save time, find patterns, and make information easier to work with. We also need to know what their results can and cannot tell us.
This guide gives us a beginner-friendly way to understand the core ideas, see where they appear, and try a small project. A token is a unit of text, such as a word, part of a word, or punctuation mark, that a model processes.
Key Takeaways
- NLP helps computers work with written text and speech.
- Natural language understanding interprets input; natural language generation creates output.
- Models turn text into numbers before many kinds of analysis.
- Language systems can make mistakes when context or input is unclear.
- Small projects can teach us how to test a model’s results.
Treat an NLP result as a useful interpretation to check, not automatic proof that a system understood us.
What Is Natural Language Processing (NLP)?
Natural language processing is the field of building computer systems that work with human language. In practice, NLP draws on computational linguistics, statistical modeling, machine learning, and deep learning.
NLP is part of artificial intelligence and computer science, but it also draws on linguistics. Linguistics studies language, while computer science focuses on designing computational systems. NLP brings methods from these areas together to process written text and speech.
A system can process patterns in language without understanding meaning as a person does.
The broad field includes different jobs, from interpreting a request to turning spoken words into text. These jobs can work together, but they do not produce the same result.
| Area | Main focus | Typical output |
|---|---|---|
| NLP | Computer methods for human language | Label, prediction, or text output |
| NLU | Interpreting language meaning | Intent or meaning label |
| NLG | Producing natural language | Readable text |
| Speech recognition | Converting spoken audio to text | Text transcript |
Speech recognition turns audio into text, which can then become input for an NLP system. A voice assistant, for instance, may first transcribe a spoken request before deciding what the words mean.
Natural language processing in artificial intelligence can support many kinds of computer tasks. Still, processing language does not prove that a system has human-like awareness or judgment.
A useful test is whether a system is analyzing language, generating it, or converting speech into text.
How Do Understanding and Generation Differ?
A system that reads a request and one that writes a reply perform different jobs, even when they appear in the same conversation. The difference is whether the system interprets input or produces language.
Natural language understanding (NLU) focuses on interpreting intended meaning; natural language generation (NLG) produces text. Many language systems use both, but neither job alone guarantees a correct result.
How NLU interprets meaning
NLU uses wording and context to estimate what a person means or wants. If someone types “Book a table,” the system may identify a request to make a reservation.
The words alone do not say how many people will attend or when they want to eat. An assistant may need to ask for those details before it can act.
Speech recognition is a separate task that can come first. It converts spoken audio into text, giving an NLU system words to interpret.
How NLG produces language
NLG turns a system’s data or decision into a readable response. After a reservation system records a booking, NLG could create a confirmation that states the time and party size.
A useful response depends on the information the system has. If the booking record contains the wrong date, clear wording will not fix that error.
Many assistants combine NLU and NLG in one exchange. They interpret a request, use a system or data source, then produce a reply in natural language.
A generated sentence can sound confident and still be incorrect. Fluent wording shows that a system can form language, not that its facts are true.
Check whether an application needs to interpret a user’s intent, produce language, or do both.
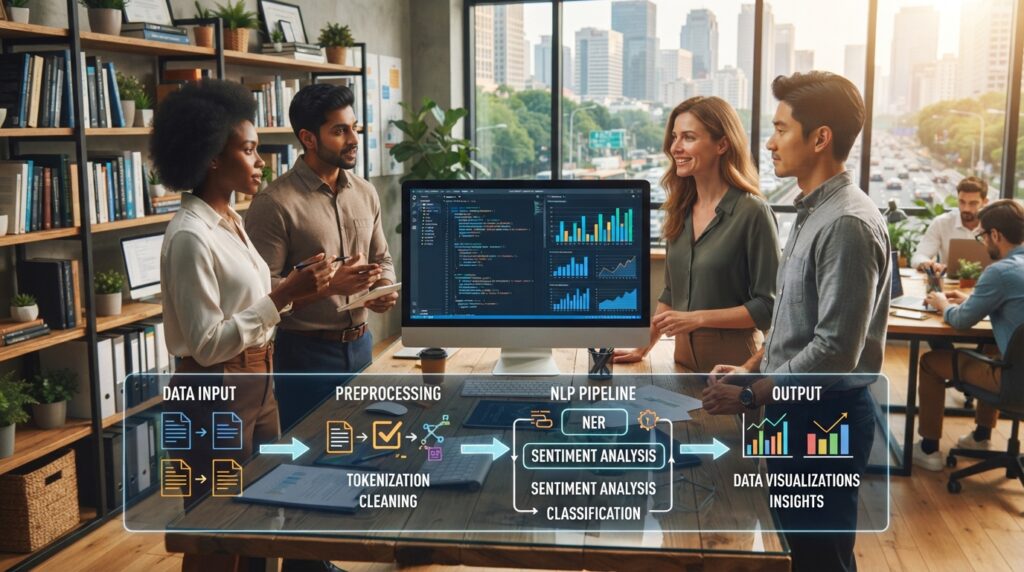
What Happens Inside an NLP Pipeline?
A customer message such as “My order is late” starts as ordinary text, not as a number a model can calculate with. Before analysis, a system may clean the text and prepare it for a model.
A typical NLP process changes text into a usable form, runs a task-specific model, and checks the result. The exact steps depend on the task and the kind of input.
Preparing and splitting the input
Tokenization splits text into tokens. A token is a unit of text, such as a word, part of a word, or punctuation mark, that a model processes.
Preprocessing may normalize letter case, remove extra spaces, and split text into sentences. Some systems remove stop words, which are common words such as “the” or “and.”
Stemming shortens a word toward a basic form, while lemmatization maps it to a dictionary form. Removing common words can harm a task when those words carry meaning, as “not” does in “not good.”
Turning words into usable features
A model often needs a numeric representation of text. A vector is a numeric representation of text that a model can use in calculations.
Bag-of-Words represents text by counting words. TF-IDF gives words a score based on how often they appear in a document and across a collection of documents.
Word2Vec and other embedding methods represent words as vectors. These representations can capture patterns in how words appear together, rather than only counting each word.
Analyzing text and producing an output
A model may analyze grammar, meaning, context, or intent, depending on the task. It then predicts a label or produces a response, summary, or other output.
Teams evaluate the result against examples with known answers. A prediction can look useful but still fail on new messages or unusual wording.
We can describe a basic process in five steps:
- Collect the text or speech input.
- Preprocess the input for the task.
- Represent the text numerically.
- Run the task-specific model.
- Evaluate the output against known examples.
Inspect the cleaned input before training, because a preprocessing choice can remove information the task needs.
Which NLP Tasks Do Computers Perform?
One sentence can be labeled by topic, checked for tone, or searched for names and places. Each task returns a different kind of result.
We should choose an NLP task by the output we need, not by the model’s name. One message may support several tasks, but their answers do not serve the same purpose.
Classifying tone, intent, and entities
Text classification assigns a label, such as “billing” or “delivery.” Sentiment analysis estimates whether text expresses a positive, negative, or neutral tone.
Named entity recognition finds items such as people, places, organizations, and dates. Word-sense disambiguation selects the intended meaning of a word with multiple meanings by using its context.
For example, “make a cake” and “make a decision” use “make” in different senses. The primary purpose of word sense disambiguation in NLP is to select the meaning that fits the surrounding words.
A message saying “The package arrived late” could receive a delivery label and a negative sentiment score. A system may also extract the package date if the text includes one.
Translating, retrieving, and answering
Machine translation changes text from one language to another. Information retrieval finds relevant documents or passages, while question answering gives a response to a specific question.
These tasks can work together. A search system might retrieve a return policy, then a question-answering system could find the passage about refunds.
Summarizing and generating text
An extractive summary selects important passages from the source. An abstractive summary restates the main meaning in new words.
Text generation creates new language from a prompt or other input. Text prediction estimates what word or phrase might come next, as a phone keyboard does.
For example, a system can shorten a long customer note into two key points. Another can suggest the next word as we type a reply.
Match the task to the result needed, since a summary, a label, and an answer are not interchangeable outputs.
Where Do We Encounter NLP in Everyday Life and Work?
A suggested reply on a phone is a small, familiar example of a system predicting language from context. Many daily tools use similar methods behind the scenes.
NLP helps people and organizations sort, search, and respond to language at scale. Its results can save time, but each use still depends on the task and the quality of the input.
Everyday typing, search, and assistants
Predictive typing suggests words based on what we have written. Spell-check and autocorrect flag or change likely errors, while spam filters sort messages by their content.
Search tools use language clues to match a query with useful pages. Translation tools such as Google Translate convert text between languages.
Voice assistants such as Amazon Alexa, Apple Siri, and Microsoft Cortana can use speech recognition and NLP to respond to spoken requests.
Customer conversations and market insight
Sentiment analysis can group customer reviews or social posts by tone. A team may use those groups to spot repeated praise or complaints about a product feature.
The system does not read every opinion correctly. Sarcasm, slang, or a short comment can change the tone a model predicts.
Some businesses use language tools to classify and route customer messages, summarize notes, or pull details from invoices. Teams exploring AI automation software for business workflows may see these text tasks linked to follow-up actions.
Documents across industries
In finance, software can extract invoice details for staff to check. Healthcare teams may use text tools to summarize records or organize notes.
Insurance teams can sort claims, while legal staff can group documents by topic or pull key details. Each task should fit the rules and review needs of its workplace.
Common settings and uses include:
- Personal devices: predictive typing and spell-check.
- Search: matching a query with relevant information.
- Customer support: routing messages by intent.
- Document handling: extracting invoice details.
- Market analysis: finding patterns in reviews.
Review a sample of automated classifications before using them to make customer-facing decisions.
How Do Rule-Based, Statistical, and Neural Approaches Differ?
A fixed grammar rule, a classifier trained on examples, and a neural model can all handle text, but they do not learn in the same way. The main difference is how each method reaches an answer.
Rule-based systems follow written instructions, while statistical and neural systems learn patterns from data. The best fit depends on the task, available examples, and need for clear rules.
| Approach | How it works | Useful when | Main limitation |
|---|---|---|---|
| Rule-based | Follows preprogrammed rules | Rules are clear or examples are scarce | Can miss varied wording |
| Statistical | Estimates patterns from examples | Labeled examples are available | Can reflect gaps in training data |
| Neural | Learns layered representations from data | Large or varied data supports the task | Can be harder to explain |
Rule-based methods can be easy to inspect because people write the instructions. A system might flag a message that contains a fixed phrase or follows a known format.
These rules still have a role when the task is limited and exact conditions matter. They can also help when training examples are scarce or labels are not ready.
Statistical NLP uses machine learning to estimate likely patterns from examples. A classifier could learn which words often appear in messages labeled “urgent.”
Neural networks learn layers of numeric patterns from data. Deep learning uses these networks to represent more complex relationships in text.
Learned systems can handle varied wording better than a short list of rules. They may also repeat patterns or bias found in their training data.
Teams can combine approaches, such as using rules for a firm safety check and a learned model for flexible language. That choice adds value only when each part has a clear job.
Our beginner’s guide to machine learning explains how models learn patterns and why testing on new examples matters.
Choose the simplest approach that can meet the task’s accuracy and maintenance needs.
How Do Language Models and Transformers Work?
A language model can begin a reply by estimating which token is most likely to follow the prompt. Repeated estimates can form a longer string of text.
A transformer uses tokenization and self-attention to model relationships among parts of language. GPT models use the decoder part of a transformer and predict the next token in a sequence.
From tokens to self-attention
A model first divides its input into tokens. A token may be a whole word, part of a word, or punctuation, depending on the tokenizer.
Self-attention helps a transformer weigh how tokens relate to other tokens in the input. In a sentence, that can help a model connect a pronoun with a name mentioned earlier.
The model works with numeric vectors rather than human ideas. These values help it detect patterns in language, but they do not prove that it knows what a sentence means.
Why GPT predicts the next token
GPT models use a decoder that estimates a likely next token from the earlier sequence. The model adds a token, then repeats the prediction to continue the text.
This process can produce a paragraph, answer, or story from a prompt. It does not look up every statement in a verified record before writing.
ChatGPT is a chatbot released in late 2022 using GPT-3.5. It applies language models through a chat interface, which makes the tool easy to use.
A likely next token is not the same as a verified fact. A chatbot can make a smooth reply that contains a false claim or misses a key detail.
Verify important claims against dependable information rather than relying on fluency alone.
What Can NLP Systems Get Wrong?
“That’s sick” can express admiration or illness depending on who says it and what came before. Context changes meaning, and a system may miss the clue.
NLP systems can make errors when language is unclear, input differs from training data, or examples carry bias. We can test how well a system works for the people and situations it will serve.
Ambiguity and context
A word can have more than one meaning, and a sentence can depend on earlier details. Idioms may also use words in ways that a literal reading misses.
Sarcasm can reverse the apparent tone of a sentence. “Great, another delay” may sound positive to a simple system, even when the writer means the opposite.
Missing context creates another problem. A short reply such as “That works” might agree with a plan, describe a tool, or refer to something said earlier.
Bias and uneven input quality
Training data can reflect unfair or incomplete patterns. A model may then give different results for people whose language appears less often in its examples.
Systems may struggle with accents, dialects, slang, misspellings, grammar variations, new words, or noisy audio. A speech system could mistake words when background noise masks part of a sentence.
Test outputs on examples from the people and situations the system will serve. Include different accents, writing styles, and real message types, not only clean sample text.
For a high-impact task, set a route for a person to review a result or correct it. Human review can catch errors that an automated score misses.
Keep a human review option for decisions that affect access, money, health, or employment.
Which Python NLP Tools Should Beginners Try?
A beginner sorting a few hundred comments may need a different tool from someone loading a pretrained transformer. Start with the task, then pick the library that fits.
Hugging Face Transformers suits pretrained models, spaCy suits language pipelines, NLTK suits learning, and Gensim suits word vectors and topic modeling. A large pretrained model may be unnecessary for a small, rule-defined task.
| Library | Best fit | Useful capabilities | License |
|---|---|---|---|
| Hugging Face Transformers | Pretrained models and task pipelines | PyTorch, TensorFlow, JAX; BERT, GPT, RoBERTa, T5, LLaMA; classification, translation, question answering, generation | Apache 2.0 |
| spaCy | Production-oriented language pipelines | 70+ languages; trained pipelines for 25; tokenization, sentence segmentation, tagging, entity recognition, dependency parsing | MIT |
| NLTK | Learning and working with corpora | 50+ corpora and lexical resources, including WordNet; tokenization, stemming, lemmatization, tagging, parsing, classification, sentiment analysis | Apache 2.0 |
| Gensim | Word vectors and topic modeling | Word2Vec, FastText, Doc2Vec, Latent Dirichlet Allocation | GNU Lesser General Public License |
Transformers offers a unified API for many model types and supports PyTorch, TensorFlow, and JAX. Its task pipelines can handle classification, translation, question answering, and generation.
The four libraries’ capabilities and licenses differ, so the right choice depends on the code and data we plan to use.
spaCy supports more than 70 languages and has fully trained pipelines for 25. Its tools include tokenization, sentence segmentation, part-of-speech tagging, named entity recognition, and dependency parsing.
NLTK gives learners access to more than 50 corpora and lexical resources, including WordNet. It also includes methods for tokenization, stemming, lemmatization, tagging, parsing, text classification, and sentiment analysis.
Gensim includes Word2Vec, FastText, Doc2Vec, and Latent Dirichlet Allocation for topic modeling. Each library is free and open source under the license shown in the table.
Start with one library that matches the task, then add another only when its capabilities solve a real gap.
What Should You Learn Before Building NLP Projects?
A beginner can explore text classification before mastering every mathematical detail behind a language model. Basic practice with Python and text data gives us a workable start.
Python basics and introductory statistics are enough for many first NLP experiments. Advanced calculus is not a prerequisite for every small text project.
Programming and quantitative foundations
Learn how to use variables, loops, functions, lists, and files in Python. Then practice reading a text file, counting words, and changing simple data structures.
Basic statistics helps us understand counts, averages, and how to compare results. We can build these skills gradually while working with small text samples.
Python can be learned in three months for basic scripting if we practice regularly and keep the goal narrow. Mastery takes longer, since larger programs and advanced models require more work.
Reading courses and research
A journal article’s abstract summarizes its question, approach, and findings. We can scan the abstract first, then read the full paper when its methods or results fit our project.
Stanford CS224N covers deep learning for NLP and research on large language models. Students complete assignments and a final PyTorch project.
The course lists Python proficiency, college calculus, linear algebra, and basic probability and statistics as prerequisites. Machine learning foundations are recommended, but not required.
The Stanford CS224N course page describes its content and assignments. Learners can use it to judge whether the course fits their current skills.
Some research papers use dense terms and equations, so we can begin with the abstract and note unfamiliar ideas. A short study session can still answer one useful question.
Set a small weekly goal, such as writing and evaluating one short text-processing script.
How Can You Start a First NLP Project?
A useful first project answers one bounded question, such as whether a short review expresses positive or negative sentiment. A narrow goal makes the result easier to test.
Use labeled reviews, a simple baseline, and evaluation examples that the model never sees during training. That gives us a fair first check of what the model learned.
Choose a narrow question and dataset
For a small sentiment project, collect reviews labeled positive or negative. Each label needs a consistent meaning, or the model will learn from mixed examples.
Read a sample before training. Check whether the text includes blank reviews, duplicate entries, unclear labels, or details that do not belong in the task.
Build a baseline and evaluate it
We can follow five steps to build and check a first version:
- Define the question and the labels.
- Inspect and clean the examples.
- Split training and evaluation data.
- Build a Bag-of-Words or TF-IDF baseline.
- Review errors and improve the approach.
Keep evaluation examples separate from training data. If examples leak across both groups, the test can look better than the model’s performance on new reviews.
A simple model can use Bag-of-Words or TF-IDF features to represent each review. We can then compare its predictions with the labels we already assigned.
Accuracy shows the share of predictions the model got right. It can hide problems when one label group has many more examples than another.
Also check false positives and false negatives. In this project, a false positive might label a negative review as positive, while a false negative misses praise.
Read several incorrect predictions by hand before changing the model, so we know what kind of error we are trying to fix.
What Careers Use NLP, and What Can They Pay?
NLP skills can support roles that build models, analyze data, or apply language technology to a specific industry. Job duties vary by employer and team.
The 2025 U.S. median annual wage for software developers was $135,980. This broad occupation figure is not an NLP-specific salary or a promise of individual pay.
Roles that work with language data
NLP engineers may build or connect systems that process text and speech. Machine learning engineers may train models, test results, or maintain the systems that use them.
Data scientists can study language data to find patterns and answer business questions. Computational linguists may work on how computers represent language and its structure.
Some roles focus on a field such as healthcare, finance, or legal work. A team may need people who understand both software and the terms used in that field.
Job titles do not always describe the same work. One NLP role may focus on software, while another may center on data, research, or product needs.
What the wage figure does and does not mean
The software developer median includes a broad range of jobs, not only language technology roles. It does not tell us what every NLP worker earns.
Compensation can change with the employer, location, experience, and role. A position that needs advanced model work may ask for different skills from one that applies existing tools.
We can compare job listings by their daily duties, tools, and required background. That gives us a clearer view of the work than a title alone.
A broad occupation median is a benchmark, not a personal pay forecast.
Compare actual job duties with the skills you want to develop before choosing a role to pursue.
Conclusion
NLP is a set of practical methods for working with human language, not a guarantee that a computer understands every message. Useful results depend on context, data quality, and careful evaluation.
We can start without building a large model or mastering every theory. Choose a narrow task, use a suitable Python library, and inspect where the system makes mistakes.
A small baseline gives us something concrete to test and improve. Choose one small text task and build a baseline you can evaluate yourself.