A spam filter that learns which messages to flag offers a familiar example of a system learning from data. It can notice patterns in words, then predict whether a new message belongs in the spam folder. We use similar models for many tasks, from sorting images to producing text. They learn from examples rather than following only a list of rules written by a person. The name comes from a loose link to the brain: software units were inspired by biological neurons, but they do not work just like a human brain. This guide explains the basic idea, how learning works, the main types, common uses, and important limits. We will also see why testing matters before we trust a result. A neural network’s usefulness depends on the patterns in its training data and the task it is built to perform.
Key Takeaways
- Neural networks learn patterns from examples and use them to produce outputs.
- Weights and biases shape how numerical signals move through a model.
- Training aims to lower loss, a measure of prediction error.
- Different network designs suit different forms of data and tasks.
- Good test results do not prove that every output is correct.
- Data quality and task design affect what a model learns.
What Are Neural Networks in AI?
Neural networks are machine-learning models that transform input data into a prediction or other output. They are a subset of artificial intelligence, or AI, and can handle tasks such as classification and prediction. In plain terms, the model uses connected artificial neurons, also called nodes, to process numerical signals. A neural network is a mathematical model, not a digital brain.
Stanford HAI’s definition describes connected layers of artificial neurons that process information through weights and activation functions. A model may take numbers, pixels, or encoded words as input. It then produces an output, such as a label or a score. The design is useful because the model can learn which patterns in data help with a task.
A neural network is a mathematical model made from connected numerical units, not a digital copy of a brain.
The word “neuron” points to a loose biological analogy. Artificial neurons work with numbers and simple rules, while biological neurons use complex electrochemical activity. Their shared name does not mean they share the same structure or purpose. A model can be trained to classify images without having human senses or thoughts.
A network with at least two hidden layers is called a deep neural network. Deep learning uses these layered models to learn patterns from data. For a beginner’s view of how machine learning fits into wider AI, see our guide to machine learning. Their brain-inspired name describes a loose analogy, not a digital copy of a human brain.
How Do Neurons Turn Inputs Into Outputs?
In a basic network, inputs enter one side, pass through hidden layers, and leave as a prediction at the output layer. The input layer receives values, hidden layers process them, and the output layer gives the result. Each step changes the numerical signal in a way the model can learn. Weights control how strongly each input affects the next calculation.
A neuron combines its incoming values with weights and a bias, or offset. A high weight gives an input more influence; a low or negative weight can reduce its effect. The bias shifts the result before the neuron sends it onward. Think of weights as volume controls that turn input signals up or down, not as signs of understanding.
An activation function is a mathematical rule that adds nonlinearity to a neuron’s weighted input before the neuron passes a signal onward. Without nonlinearity, a network would struggle to learn curved or layered patterns. ReLU, sigmoid, and tanh are common activation functions. ReLU sets negative values to zero, while sigmoid maps values to a range between zero and one.
The output depends on the task. A classification model may produce a score for each label, while a prediction model may return one number. The network’s input layer, hidden layers, and output layer work together to turn data into that result. Small changes in weights can alter the output, especially when many layers connect.
Each neuron applies a simple calculation, yet many connected neurons can represent complex relationships. Without a nonlinear activation, stacking layers would not give the network the same ability to learn complex relationships. That is why activation functions matter even though they do not make a neuron think.
How Does a Neural Network Learn?
A network learns by making a prediction, measuring its error, and adjusting its parameters to reduce that error. Training commonly changes weights and biases to lower a loss function, which measures prediction error. The cycle repeats across many examples. Backpropagation is common for differentiable networks, but it is not a universal learning method for every neural architecture.
- The forward pass sends input data through the network and produces a prediction.
- Loss compares that prediction with the correct target for the example.
- Backpropagation calculates parameter gradients, or how each parameter affected the loss.
- An optimizer updates weights and biases to reduce the loss.
Backpropagation uses the chain rule to trace how changes in earlier parameters affect later calculations and the final error. It does not tell the model what a picture or sentence means. It gives the optimizer information about which parameter changes may improve the prediction.
Gradient descent is one optimization method. It adjusts parameters in the direction that should lower loss, often using a step size called the learning rate. A step that is too large can miss a better setting, while a step that is too small can make training slow. Different optimizers use different ways to adjust those steps.
Training applies this process across examples, often more than once. A set of examples used to fit the model is training data. We also evaluate the model on separate data it did not train on. That test helps us see whether it learned a useful pattern or merely fit familiar examples.
Evaluation on separate data checks whether the model can generalize to unfamiliar cases. That distinction matters because a low training loss alone can hide poor real-world performance. Training performance alone is not enough, because a model must also work on examples it did not train on.
What Does a Neural Network Example Look Like?
An email that says “Get free gift cards now!” can be converted into a few numerical features for a simple classification example. We can track whether it contains “free,” “win,” and “offer.” The model receives those values as input and calculates a spam score. Here is one small example, not a real filter. The values below illustrate a calculation, not a trained production system.
A feature vector records the presence of each word in a fixed order. A value of 1 means the word appears, while 0 means it does not. Hidden neurons combine those features using weights and biases, then apply ReLU. The final neuron uses a sigmoid function to turn its score into a probability between zero and one.
- Input features for “free,” “win,” and “offer”: [1, 0, 1].
- First hidden-neuron output after ReLU: 0.8.
- Second hidden-neuron output after ReLU: 0.
- Final spam probability after sigmoid: about 0.636.
- Classification at a 0.5 threshold: spam.
The zero in the input means “win” is absent. The hidden outputs show how two neurons respond to the full set of features, not just one word. The final probability is above the chosen threshold, so this example assigns the spam label.
A threshold changes a probability into a label, but it does not prove the label is right. One message could contain “free” in a harmless offer or mention spam as a warning. A real filter would need training and testing on many messages. The threshold turns a probability into a label, while a real filter would need training and testing on many messages.
What Are the Three Ways Neural Networks Learn?
The key difference among these learning setups is the kind of feedback the model receives. Supervised learning uses labeled examples, unsupervised learning finds structure without labels, and reinforcement learning uses rewards or penalties. The feedback signal helps us identify the setup. These are learning setups, not separate neural-network architectures.
| Learning setup | Training signal | Typical goal | Example |
|---|---|---|---|
| Supervised | Known labels | Classification | Labeled cat-and-dog images |
| Unsupervised | No labels | Discover structure | Clustering similar records |
| Reinforcement | Rewards or penalties | Improve actions over time | A game-playing agent |
In supervised learning, each example pairs an input with a known answer. A model might learn to sort labeled animal pictures into cat and dog groups. Unsupervised learning works with raw examples and looks for patterns, such as groups of similar records, without being told the correct groups.
Reinforcement learning learns through actions and feedback from an environment. A game agent may gain a reward for a useful move and a penalty for a poor one. It can improve its choices over many rounds, even when no person supplies a label for each action.
We can sort a new task with three quick checks:
- Does each example come with a known label or answer?
- Are there only unlabeled examples, with structure to discover?
- Does the model act and receive rewards or penalties?
These questions help us choose a training setup before selecting a model. The source of feedback shapes what the system can learn. Before choosing a method, check whether the task already has labels, has only raw data, or provides rewards for actions.
Which Three Architectures Should Beginners Know?
Feedforward networks suit straightforward input-to-output tasks, CNNs suit spatial patterns, and RNNs or transformers suit sequential information. These are four common designs, though they are not the only architecture families. Structure guides the choice: image pixels and ordered words pose different problems. Transformers are not recurrent networks, even though both can process sequences.
Feedforward networks pass information in one direction
A feedforward neural network sends data from input to output without cycles. Its layers pass signals in one direction, and common training uses backpropagation. A simple model can classify rows of measured features or predict a value from a fixed set of inputs.
Because the model does not keep a state from one moment to the next, it does not naturally track a sequence as it unfolds. The input must be represented in a form the network can use. A small feedforward model is often a clear first architecture to study.
CNNs detect spatial patterns in grid-like data
Convolutional neural networks, or CNNs, use convolutional layers to scan for local patterns. These layers can detect features such as edges and shapes in grid-like data. Images and video are common fits because nearby pixels often form meaningful visual details.
A CNN can learn simple visual features in early layers and combine them into more complex ones later. It does not need a person to list every edge or shape in advance. The design uses the spatial layout of the input rather than treating every pixel as unrelated.
RNNs and transformers handle sequence information differently
Recurrent neural networks, or RNNs, keep an internal state as they process a sequence. That state can carry information from earlier steps into later ones. Long sequences can be hard to train, in part because gradients may vanish as they move backward.
Transformers use self-attention to compare parts of an input and can process many parts in parallel. This helps them capture long-range links in a sequence. They do not pass a hidden state from one time step to the next like an RNN.
Each architecture builds on a different view of the input: fixed values, spatial grids, or sequences. That fit matters more than the name’s popularity. Choose an architecture for the structure of the data, not because one family is automatically best for every task.
What Other Types of Artificial Neural Networks Are There?
Specialized network designs change how information is represented or compared to suit a particular task. Autoencoders learn a compact form of an input, while other models compare examples, generate content, or process spikes. Each design has a job. These families are not interchangeable just because they all use neural networks.
Some networks compress data or map its structure
An autoencoder has an encoder and a decoder. The encoder turns input into a smaller latent representation, and the decoder tries to rebuild the original input from it. That process can support denoising, anomaly detection, or data compression.
For denoising, an autoencoder learns to rebuild a cleaner version from a noisy input. For anomaly detection, unusual inputs may produce larger reconstruction errors than familiar ones. The model does not know that an example is “bad” by itself; people decide how to use its output.
A self-organizing map places data in a lower-dimensional space while trying to preserve relationships among nearby examples. It can help people view structure in complex data. A two-dimensional map, for example, can show which records are alike without displaying every original feature.
Other networks generate, compare, or process spikes
A generative adversarial network, or GAN, pairs a generator with a discriminator. The generator makes samples, while the discriminator judges whether samples resemble the training data. Training both parts can help the generator produce more convincing examples.
A Siamese neural network compares two inputs using matching network branches with shared weights. It can learn whether two images or records are alike, rather than assign each one a separate label. The shared weights keep both sides using the same learned rules.
Spiking neural networks communicate through discrete spikes rather than only continuous values. This approach is studied in neuromorphic computing, which builds systems inspired by some features of brain activity. The signal format changes how the model processes information, so it suits different hardware and tasks.
These designs solve distinct problems: one may rebuild data, another may compare pairs, and another may generate samples. Start with the task’s data and desired output before choosing among these less familiar architectures.
What Are Neural Networks Used For?
Neural networks are useful wherever a system must learn patterns from data such as images, language, sound, or measurements over time. The input and desired output help shape the model choice. For example, a vision system may receive pixels and return an object label. The same model type does not fit every kind of input.
| Application | Typical input | Common network approach | Example output |
|---|---|---|---|
| Computer vision | Images or video | CNN | Object label |
| Natural language processing | Text | Transformer | Translation or summary |
| Speech recognition | Audio | Sequence model | Transcript |
| Forecasting | Time-series measurements | Feedforward or sequence model | Future value |
Computer vision systems can scan image or video data for patterns and return labels or locations. Natural language processing systems work with text, such as translating one language into another or drafting a summary. These outputs depend on how the model represents the input and what it learned during training.
Speech recognition turns audio into text. A sequence model can use the order and timing of sound signals to predict words. Forecasting models use past measurements, such as readings over time, to estimate a future value. Their predictions depend on whether the patterns continue.
Robotics and game-playing can combine neural networks with reinforcement learning. A model may help an agent choose actions, while rewards guide its later choices. The task still sets the test: a game score cannot show how well a robot handles a real room. A familiar application is not proof that every system in that field uses a neural network.
How Are Artificial Neural Networks Different From the Human Brain?
Artificial neural networks borrow a few ideas from biology, but their units and learning rules are simplified mathematical constructs. Biological neurons use electrochemical activity; artificial neurons process numerical values. The name is an analogy, not proof that the two systems work alike. A software neuron is not a biological neuron.
| Aspect | Biological neuron | Artificial neuron |
|---|---|---|
| Signal | Electrochemical activity | Numerical value |
| Connections | Synapses | Weighted links |
| Learning | Biological processes | Parameter updates |
| Purpose | Activity within a living brain | Task-specific computation |
The difference matters when a model completes a task linked to brain function. MIT researchers trained more than 11,000 neural networks on path integration, a task that tracks movement through space. Nearly 90% learned it successfully, yet only about 10% of those successful models showed grid-cell-like activity.
The researchers said that grid-cell-like activity depended on specific constraints they described as biologically implausible. A model can reach the right answer through a process unlike the brain’s process. Success alone does not reveal which internal steps led to the result.
A 2022 MIT report cautioned that task performance alone does not establish useful predictions about brain function. The result gives us a reason to be careful when comparing artificial models with living brains. A model that performs a brain-related task does not, by itself, explain how the brain performs it.
How Do Transformers Connect to GPT and ChatGPT?
ChatGPT is a product built around GPT models, and GPT models are neural networks based on the transformer architecture. GPT stands for “Generative Pre-Trained Transformer.” The name describes the model family, while ChatGPT names a conversational product. ChatGPT and GPT are related, but they are not the same thing.
The transformer architecture appeared in the 2017 paper “Attention Is All You Need.” GPT models are a type of large language model, or LLM, that uses this architecture. They train on large datasets and learn to predict the next token, a piece of a word or other text unit.
“Generative” refers to producing text, “pre-trained” means the model first learns from a large collection of data, and “transformer” names its architecture. OpenAI introduced GPT-1 in 2018. ChatGPT launched on November 30, 2022, initially using GPT-3.5.
The product can use a GPT model in a chat interface, but the interface and the model are different parts of the system. A chat product may also include tools and other features. Its fluent text can still contain errors because next-token prediction does not guarantee truth.
In February 2026, ChatGPT had 900 million weekly active users. That figure shows broad use, not whether a reply is accurate, safe, or suitable for a particular task. Popularity measures reach, not the quality of every answer. A large user base shows widespread use, not that every response is correct or reliable.
What Can Neural Networks Do Well?
Neural networks are especially useful when important patterns are complex, nonlinear, or difficult to specify by hand. Activation functions help layered models represent nonlinear relationships. That flexibility can help with tasks where a simple fixed rule misses key patterns. Layered models can learn features from data instead of relying only on hand-designed features.
A model can learn which details matter by adjusting its weights during training. It may first find simple patterns, then combine them into richer representations. This feature learning can reduce the need for people to define every useful input signal in advance.
Neural networks also perform many calculations in parallel. Graphics processing units, or GPUs, can speed up these calculations during training. A faster computer does not fix poor data or a poorly chosen task, but it can help process larger models and datasets.
- Combine many input features to make one prediction.
- Learn intermediate representations from examples.
- Scale parallel calculations on GPUs.
These capabilities matter when the examples reflect the problem we want to solve. A model trained on narrow or flawed examples may learn the wrong patterns with great confidence. Capacity alone does not make a system useful. Their capacity is valuable only when the training examples represent the task we want the model to perform.
What Are the Main Limitations of Neural Networks?
A model can perform well on its training data and still make unreliable predictions on new cases. This is called overfitting: the model fits familiar examples too closely instead of learning patterns that generalize. Good training scores can mislead. Check performance on examples the model did not train on.
Overfitting can make training results misleading
Overfitting often appears when a model learns details that do not carry over to new examples. A network may memorize unusual features in its training data rather than learn the patterns needed for future cases. Comparing training and held-out results can reveal this gap.
Large models can also need substantial computing power and large datasets. Gathering enough useful examples may take time and cost effort. Even a large dataset can fall short if it misses the people, settings, or conditions where the model will be used.
Data, computation, and interpretability set practical limits
Neural networks can be hard to interpret because many weights interact to produce an output. A score may show what the model predicts without explaining why it chose that answer. This opacity matters when people need to understand how a decision was made.
Biased or unrepresentative training data can carry bias into model outputs. For instance, a system may work less well for a group that appears less often in its examples. The model’s output can also seem more certain than its evidence supports.
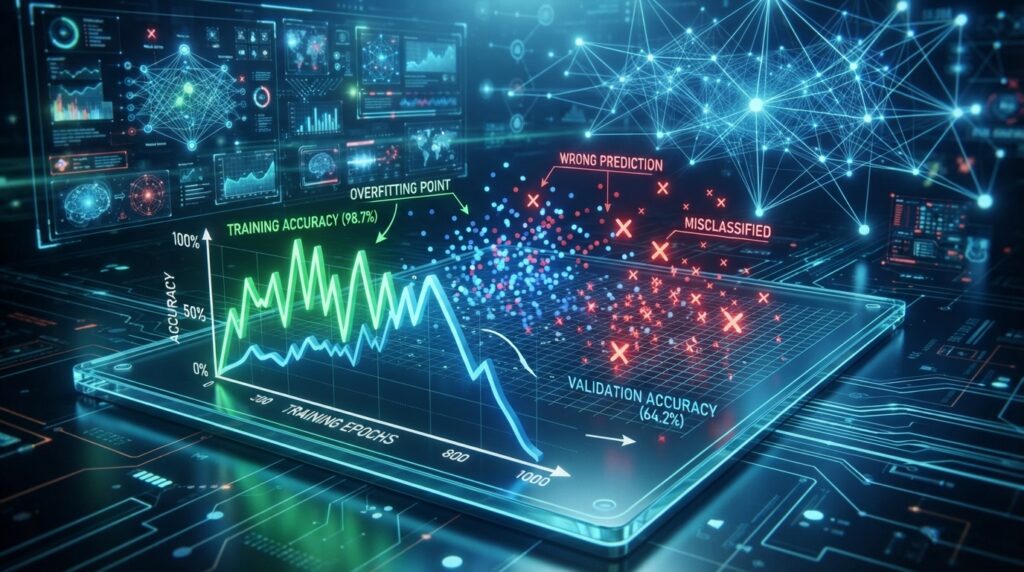
We can use this four-point check before relying on a result:
- Compare training performance with held-out performance.
- Check whether examples cover relevant cases.
- Inspect errors across groups and conditions.
- Require human review for consequential decisions.
For practical ways AI can fail through incomplete data or fluent but wrong output, see how AI fits into daily work. A confident score is still a prediction. Treat a confident output as a prediction to check, not an explanation of why the model is right.
How Should We Judge Neural-Network Results?
A benchmark measures performance on a defined test, not general intelligence across every task. In March 2026, the top six Arena Elo ratings were Anthropic 1,503, xAI 1,495, Google 1,494, OpenAI 1,481, Alibaba 1,449, and DeepSeek 1,424. That ranking has limits. A single score cannot tell us how a model handles every real task.
| Test or measure | AI result | Comparison or caveat | What it tests |
|---|---|---|---|
| Arena Elo | Six lab ratings | Not a universal measure | Human preference |
| ClockBench | 50.6% | Humans: 90.1% | Analog-clock reading |
| OSWorld | 66.3% | Within 6 points of humans | Computer-use tasks |
| Household robotics | 12% | RLBench simulation: 89.4% | Real-world transfer |
| AI-text detectors | AUC 0.75-1.00 | No detector fully reliable | Text classification |
Invalid questions can distort benchmark results. A review cited in the 2026 AI Index found invalid-question rates from 2% on MMLU Math to 42% on GSM8K. Frontier models also gained 30 percentage points in one year on Humanity’s Last Exam, a fast gain on that test rather than proof of broad skill.
Agent scores also hide failures. AI agents still failed roughly one in three attempts on structured benchmarks. Real household robots succeeded in 12% of tasks, while robotic manipulation in the RLBench software simulation reached 89.4%. Those results show how much the test setting matters.
A study of 1,000 texts included 250 human-written articles and 750 ChatGPT-generated texts. Corrector, ZeroGPT, and GPTZero had AUC values from 0.75 to 1.00, and none was fully reliable. Human texts had the lowest AI-likelihood scores, while tested AI texts scored higher, with p < 0.01. That pattern does not prove who wrote one specific text.
In March 2026, the top closed model led the top open model by 3.3%, compared with 0.5% in August 2024. Arena Elo ratings rank models on a defined comparison, not on every task. Check what a benchmark measures, how often its items are valid, and whether its setting matches the real task.
How Can We Start Learning Neural Networks?
We can start with a small model and a clear prediction task rather than trying to understand every modern AI system at once. Basic algebra and probability support the first steps. A modest project can make the ideas concrete. Build a model, then test it on examples it has not seen.
A beginner’s learning path can move from simple math to a small neural model, then to a more complex design. TensorFlow and Keras offer tools for building neural-network examples. We do not need advanced math before writing a first classifier, though basic concepts help explain its results.
- Review vectors and probability, then practice with small numerical examples.
- Build and evaluate a small feedforward classifier on labeled data.
- Try a CNN or transformer tutorial with a held-out test set.
When choosing a neural networks book, check whether it introduces math gently and explains new terms. Worked examples help us connect equations with code. A useful book also discusses evaluation, not just training steps or model design.
A three-month study plan can provide an introduction and a small project, but it cannot promise mastery. Progress depends on prior math, study time, and practice. Steady practice is more useful than rushing through topics without testing what we learned. A completed, evaluated beginner project is a more useful milestone than simply finishing a book.
How Do Researchers Describe Neural Networks?
Neural-network research spans both computer science and questions about how biological brains process information. Warren McCulloch and Walter Pitts proposed a mathematical neuron model in 1943. That early model gave researchers a way to describe simple neural activity with mathematics. The field draws on ideas from several areas, but its models remain mathematical tools.
Frank Rosenblatt introduced the perceptron in 1958, an early model that learned to classify inputs. In 2017, the paper “Attention Is All You Need” introduced the transformer architecture. These milestones mark changes in how researchers build systems to process information.
The research field includes many questions: how models learn, which patterns they represent, and how well their results hold up. Some studies also compare model activity with brain activity. Similar results can be useful clues, but they do not make artificial and biological systems equivalent.
The journal Neural Networks is commonly abbreviated “Neural Netw.” That abbreviation names a publication, not a separate model type. Context matters when we read a title or citation, especially when a journal name resembles a field’s technical term.
“Neural Netw.” is a journal abbreviation, not another kind of neural network.
Research papers may use the journal title to name where an article appeared, while neural network describes the model family. Keep the journal title and the name of the model family distinct when reading research.
Conclusion
A neural network is best understood as a learned computational model, not a miniature human brain. It adjusts patterns from data to make a prediction or produce another output. Its results depend on the task, the examples, and how we test its performance. A system can work well on one measure and still fail in a different setting.
We can keep two points in mind: training data shapes what a model learns, and evaluation tells us where its results hold up. Start with one simple prediction problem. Trace the inputs, the output, and the examples used to test the model.
Pick one small dataset and check how a simple model performs on examples it did not train on.