A photo app recognizing a dog or an email filter flagging spam both turn data into a useful prediction. A neural network can learn to make that prediction from examples. These models can also sort items into groups, a task called classification.
We can use machine learning to find patterns in data, even when those patterns are hard to describe with simple rules. This guide explains the main ideas in plain language, with a small worked example, common applications, and limits to keep in mind. Not every AI system uses this approach.
The central idea is simple: a model improves by adjusting its internal parameters against examples.
Key Takeaways
- Connected mathematical units turn inputs into outputs.
- Weights and biases shape each unit’s calculation.
- Training adjusts those values to reduce errors.
- Different architectures suit different types of data.
- Test results on new examples before trusting a model.
What Is a Neural Network?
An artificial neural network is a machine-learning model that uses connected mathematical units to turn inputs into predictions. Its inspiration comes from the human brain, but the model does not copy a brain cell by cell. Artificial neural networks are mathematical tools, not digital brains.
A biological neural network is a group of biological neurons that pass signals through connections called synapses. A biological neuron has a cell body, dendrites that receive signals, and an axon that sends signals to other neurons. Synapses usually connect an axon to another neuron’s dendrites.
Brain biology can inspire a model’s design, but it does not show that software thinks like a person.
The human brain forms networks from about 10¹¹ neurons and about 10¹⁵ synaptic connections. These numbers describe biology, not the size of a typical computer model. An artificial network uses mathematical processing units and weighted connections to transform information.
Warren McCulloch and Walter Pitts proposed an early mathematical neuron model in 1944. Frank Rosenblatt demonstrated the trainable Perceptron in 1957. That history marks a useful difference: one was an early proposal, while the Perceptron could adjust through training.
We can read more about how artificial intelligence appears in daily work, including approaches beyond neural networks. A neural network in the brain means biological neurons connected to pass signals across synapses. The brain comparison is an analogy, not a claim of human-like thought.
Treat the brain comparison as inspiration for the design, not proof that software thinks or learns exactly as people do.
How Does an Artificial Neuron Turn Inputs Into an Output?
A neuron first combines its inputs into a weighted sum, adds a bias, and transforms the result into an activation. The weight sets how much one input matters to that connection. A bias shifts the result independently of the inputs.
Suppose two inputs are x₁ and x₂, with weights w₁ and w₂. The neuron multiplies each input by its weight, then adds the products and a bias: z = w₁x₁ + w₂x₂ + b. The value z is the weighted input before its final transformation.
An activation function is a mathematical function that transforms a neuron’s weighted input and bias into its output. That output is the neuron’s activation. An activation function can help a network represent patterns that a simple, straight-line calculation cannot capture.
ReLU, short for rectified linear unit, returns the input when it is positive and zero otherwise. If z is -0.4, ReLU returns zero; if z is 0.7, it returns 0.7. A sigmoid function instead maps any input to a value between zero and one.
For example, if a neuron’s weighted sum and bias produce z = 0.7, ReLU gives an activation of 0.7. Sigmoid gives a value near 0.668. The chosen function changes the output even when the inputs, weights, and bias stay the same.
A common mistake is to treat a weight as a measure of a whole neuron’s importance. A weight describes the effect of one connection on one input, not the value of an entire neuron. A network’s prediction depends on many such links working together.
When we compare two activations, we should check how each was calculated. Check whether an example includes its bias before comparing its activation with another neuron’s output.
How Do Layers and Neural Network Architectures Differ?
A network’s architecture describes how its layers are arranged and how information can move between them. The input layer receives features, hidden layers process them, and the output layer produces a result. Architecture should match the kind and order of the input.
Deep learning uses neural networks with multiple layers. Each layer can transform information before passing it onward. The arrangement affects processing, but a model’s name alone does not tell us whether it will work well.
Feed-Forward Networks and Convolutional Neural Networks
A basic feed-forward network passes each layer’s output to the next. It does not carry information from one input to the next. This design can suit standard feature data, such as rows of measurements used for classification or regression.
A convolutional neural network, or CNN, is built to find spatial patterns in images. It can learn features such as edges and shapes from nearby pixels. These features help the network process an image without treating every pixel as unrelated to its neighbors.
Recurrent Networks and LSTMs for Sequences
Sequence data has an order, such as words in a sentence or measurements over time. A recurrent neural network, or RNN, feeds information from one time step back into the network at the next step. That feedback can help the model use earlier inputs.
A long short-term memory network, or LSTM, is a type of RNN with an extra memory mechanism. It is designed to retain recent information longer than a basic RNN. That can help when a useful clue appears earlier in a sequence.
Transformers and Attention for Language
Transformers use attention to weigh how parts of a sequence relate to each other. They can process an entire text sequence at once, rather than handling words only in order. This design addressed performance issues linked to older recurrent approaches in natural language processing.
The table shows common uses and information flow. It offers a starting point, not a promise of accuracy. A newer architecture is not automatically a better fit.
| Architecture | Suitable input or task | Information handling |
|---|---|---|
| Feed-forward network | Feature data, classification, regression | Passes outputs forward between layers |
| CNN | Images, spatial patterns | Learns spatial features |
| RNN/LSTM | Sequences, time-series data | Uses earlier time steps; LSTM retains recent information longer |
| Transformer | Text sequences, language tasks | Uses attention to process a sequence at once |
Match the architecture to the shape and order of the input, not to the assumption that a newer design is always better.
How Does a Neural Network Learn From Data?
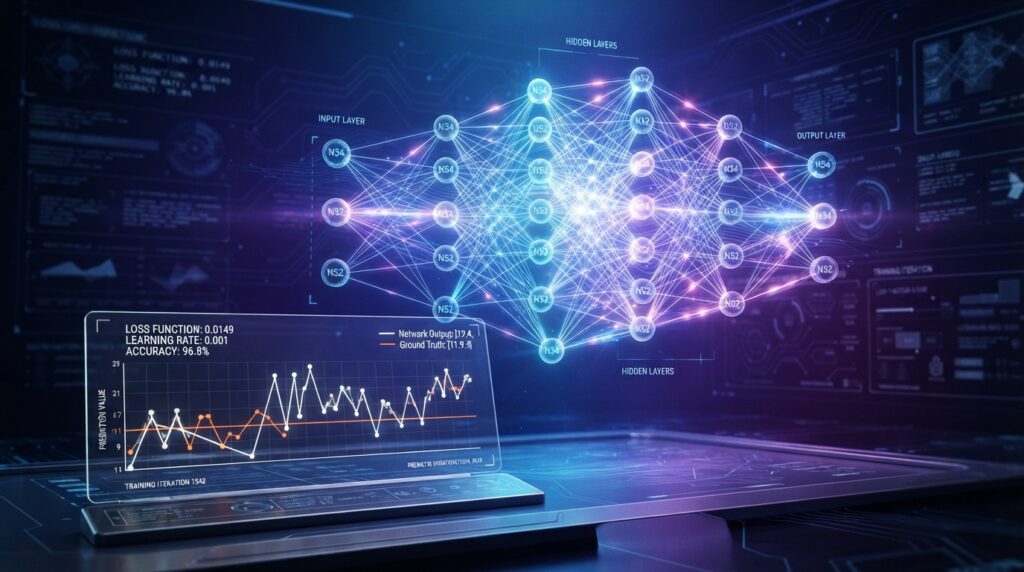
Training improves a model by repeating predictions, measuring their error, and adjusting parameters. A loss function measures how far a prediction is from its target. Training aims to reduce loss, not to guarantee perfect answers.
We can picture training as a repeated process. The model makes a prediction from data, and the loss function compares that result with the known target. A smaller loss usually means a closer fit to the examples being used.
Forward Propagation and Loss
During forward propagation, information moves through the network to produce a prediction. The loss function then measures the model’s error. The model needs examples with known targets to measure that error directly.
For example, a labeled picture might have the target “cat.” If the model gives a low score to that label, the loss can reflect the mismatch. The loss gives training a signal about how the current prediction compares with the target.
Backpropagation and Parameter Updates
Backpropagation calculates how weights and biases contributed to prediction error. It uses gradients, which show how a small parameter change would affect the loss. Gradient descent uses those gradients to update parameters in a direction that can lower loss.
The model repeats these steps across training data because one update rarely captures every pattern. An epoch is one pass through the training dataset. The number of epochs and update size affect how the model fits its examples.
A typical training loop has four stages:
- Make a prediction.
- Calculate the loss.
- Calculate gradients with backpropagation.
- Update weights and biases with an optimization method.
Supervised, Unsupervised, and Reinforcement Learning
Supervised learning uses labeled input-output pairs, such as photos marked with object names. Unsupervised learning looks for patterns in unlabeled data. Reinforcement learning uses rewards or penalties to guide actions over time.
Learning machine learning is approachable with basic algebra and coding. Calculus and linear algebra help us understand gradient-based training in more depth. A beginner can choose an introductory neural network book, an online lesson, or a structured course that includes exercises.
Michael Nielsen’s Neural Networks and Deep Learning is an example of an online book. We can use its lessons alongside small coding exercises to connect the ideas with working models. A neural network online course can add guided practice, while a book lets us study at our own pace.
Keep a separate evaluation dataset so training progress is not mistaken for performance on new examples.
What Does a Neural Network Example Look Like?
A spam filter can turn the presence or absence of a few words into a numerical input for classification. In this example, the email contains “free” and “offer,” but not “win,” producing the feature vector [1, 0, 1]. The final score crosses a chosen 0.5 cutoff.
Assume the hidden layer has two neurons. Their weighted sums are 0.8 and -0.1. ReLU turns those values into hidden outputs of 0.8 and 0, since it sets negative values to zero.
The output layer combines the hidden outputs into a weighted sum of 0.56. Applying sigmoid gives about 0.636. Since 0.636 is above the chosen 0.5 threshold, this illustrative model labels the email as spam.
This score is not proof of a calibrated real-world probability. It shows how a model can turn features into a decision using its learned weights and a decision rule. We can describe the calculation in four stages:
- Encode the words as features.
- Calculate the hidden outputs.
- Calculate the output score.
- Apply the decision threshold.
Image recognition uses a different kind of input. A 28 x 28 image can become 784 pixel values, while 10 output neurons can represent digits 0 through 9. The model’s top output can indicate which digit it predicts.
A change in the threshold can change the classification without changing the network’s score. A lower cutoff may flag more messages, while a higher cutoff may flag fewer. Treat the example’s 0.5 cutoff as a chosen decision rule, not a universal threshold for every task.
Is ChatGPT a Neural Network, and Is All AI?
ChatGPT is an AI application built on GPT models, which are neural networks based on the transformer architecture. GPT belongs to machine learning, while artificial intelligence covers a wider range of systems. Not every AI system uses a neural network.
Some AI uses hand-written rules instead of learning patterns from examples. A rule-based system might follow a set of “if this, then that” instructions. Machine learning is one part of AI, and neural networks are one kind of machine-learning model.
GPT models are large language models built on the transformer architecture. They are pretrained on large datasets of unlabeled content. During self-supervised pretraining, a model learns from the structure of the text itself, rather than relying on a person to label every example.
GPT models use the decoder part of a transformer and learn to predict the next token in a sequence. A token can be a word or part of a word. By predicting what comes next across many examples, the model learns patterns in language.
Generative pretraining is a form of self-supervised learning. Labeled data can later adapt a pretrained model to a particular task. This extra training can guide a model toward a task, but it does not turn its response into a checked fact.
Text generation is not the same as retrieving a guaranteed true answer. A model predicts a likely next token based on patterns in its training and the current input. That process can produce useful wording, but a fluent response can still contain mistakes.
A generated response is a model prediction, so important claims still need to be checked.
Where Are Neural Networks Used?
Neural networks are useful when a task involves learning patterns from images, text, sound, or other data. Their applications range from sorting images to processing speech. Results depend on the data and setting where a model is used.
Broad AI adoption has grown across daily life and organizations. Generative AI reached nearly 53% population-level adoption within three years, organizational AI adoption rose to 88%, and global corporate investment in AI more than doubled in 2025. These figures describe AI broadly, not neural networks alone.
Image Recognition and Computer Vision
Image classification assigns a label to an image, while video recognition tracks patterns across frames. Medical imaging can help analyze scans as part of a larger clinical process. A [computer vision system](https://sahabattekno.com/computer-vision-solutions-for-smarter-business-growth/) can also produce different outputs, such as object locations or image regions.
A custom CNN study evaluated scene classification on NWPU-RESISC45 and UC Merced. Its results include accuracy scores of 0.9428 and 0.93 on those datasets. It also used SHAP and Class Activation Mapping to help explain image-classification predictions.
| Metric | NWPU-RESISC45 | UC Merced |
|---|---|---|
| Accuracy | 0.9428 | 0.93 |
| F1-score | 0.94 | 0.93 |
| Precision | 0.95 | 0.94 |
| Recall | 0.94 | 0.93 |
| Intersection over Union | 0.89 | 0.86 |
The results describe those datasets, not every image a model might meet. A strong score on familiar scenes may not carry over to images taken under different conditions.
Text, Speech, and Time-Series Tasks
Neural networks support language translation, chatbots, and sentiment analysis, which estimates the tone of text. Speech recognition turns spoken words into text. Time-series models can also process measurements recorded in sequence, such as changing sensor readings.
These tasks use different input features and may need different network designs. A speech model, for example, must handle sound signals that change over time. A text model processes ordered language, while a time-series model can look for changes across measurements.
Healthcare, Finance, and Edge Devices
Healthcare teams can use networks for disease diagnosis support and medical-image analysis. In finance, models can help with fraud detection and risk management. Real-time game or autonomous-system decisions may also rely on quick processing of changing inputs.
Edge AI runs a model on or near the device that collects data. Edge AI work must balance model size, speed, energy use, and accuracy. The trade-off matters when a device has limited memory or power.
Broad AI investment does not show how much any one neural network costs or how well it works. A strong result on one image dataset does not by itself establish performance in a different setting.
What Are the Strengths and Limits of Neural Networks?
A neural network can capture complex patterns, but its training performance does not guarantee dependable predictions on new data. It can learn nonlinear relationships and useful features from examples. Overfitting makes performance on new examples less reliable.
Overfitting happens when a model fits details in its training data too closely. The model may then struggle with examples it did not see during training. Poor data quality can also teach harmful or inaccurate patterns.
A high training score alone is not evidence that a model will work well on new cases.
Training data can reflect bias in how examples were collected or labeled. A model may also be hard to interpret, especially when it has many parameters. SHAP is one method that can help explain how features affect a prediction, but an explanation aid does not prove the model is correct.
Large models can need substantial computing power and memory. That can make them hard to run on small devices. We can use this checklist before deployment:
- Inspect and clean the training data.
- Test on examples held out from training.
- Compare the model with a simpler baseline.
- Check for overfitting.
- Measure speed and memory before deployment.
Edge AI can use quantization and pruning to reduce model size or computation. We still need to check those changes against the accuracy the task requires. Transfer learning can adapt a pretrained model to a smaller task dataset.
Before deployment, test the model on representative new examples and the device where it will run.
Conclusion
A neural network is easiest to understand as a function that learns a useful mapping from examples. It passes inputs through connected layers to produce outputs, then improves by adjusting weights and biases against examples.
We can begin with a small classification task, such as sorting a few images or text samples. Keep the task simple enough that we can inspect its inputs and predictions. Then compare its results with examples it did not use during training.
Try a small image or text classification exercise, then compare its predictions with labels it never saw during training.