A photo app that recognizes a face offers a familiar glimpse of a system learning patterns from data. For beginners, that small moment raises big questions: how does a model learn, and when should we trust its result? We explain the ideas behind layered models without assuming you already know artificial intelligence. Along the way, we look at practical uses, from reading images to working with text and signals. We also consider what these systems cannot reliably do, including cases where missing data or a new setting can lead to mistakes. The aim is a clear starting point, not a promise that one kind of model fits every task. Keep one distinction in mind from the start: a confident prediction is not the same as a guaranteed correct answer.
Key Takeaways
- Deep learning is part of machine learning and artificial intelligence.
- Neural networks learn patterns through layers of processing.
- Different tasks need different model designs and outputs.
- Good results depend on useful data and careful testing.
- A prediction can be wrong, even when it sounds sure.
- Small projects can help us connect ideas with practice.
What Does Deep Learning Mean?
Deep learning is a branch of machine learning that uses multilayer neural networks to learn patterns from examples. A feature is a measurable pattern in input data that a model uses to make a prediction. Features might include edges in an image or repeated words in text.
Deep learning is a specialized form of machine learning, and machine learning is part of artificial intelligence. Artificial intelligence is the broad field of systems that perform tasks linked with human judgment. Machine learning is one approach within that field. Deep learning uses networks with multiple hidden layers to learn useful representations from examples.
A model receives an input, such as a picture, a sentence, or a set of measurements. It produces an output, such as a label, a forecast, or generated text. Training may use labeled examples, where each input has a known answer. Other methods learn from data without labels, or combine labeled and unlabeled examples.
Common neural network architectures include convolutional neural networks, recurrent neural networks, and Transformers. Each handles patterns in a different way. Training can be supervised, semi-supervised, or unsupervised, depending on the data and learning goal.
Readers who want the wider picture can explore machine learning basics and business uses. That broader field includes many methods that do not use deep networks.
A model’s output is a prediction based on its learned patterns, not a human-like explanation of how it reached that result.
For example, an image model may return “cat” because its learned features match patterns found in earlier examples. It does not need to know what a cat means to produce that label. That difference matters when we judge what a prediction can tell us.
Deep learning and AI are related, but they are not interchangeable terms. Deep learning names one family of learning methods within AI. A model’s output is a prediction based on its learned patterns, not a human-like explanation of how it reached that result.
How Does a Neural Network Learn From Data?
If a network labels a picture incorrectly, training gives it a way to adjust the parameters behind that prediction. A neural network learns by comparing its output with a known target, then changing internal values to reduce error. This process repeats across many examples.
For a simple image task, the input is a picture and the output might be “dog” or “cat.” Hidden layers process the image in stages. The network can learn useful features from examples, but people still choose its design and training setup.
Suppose the correct label is “cat,” but the network predicts “dog.” The difference between its prediction and the target is its error. Backpropagation uses the chain rule to work out how network parameters contributed to that error. Gradient descent then adjusts those parameters to reduce future error.
In image recognition, early layers can represent lines and shapes. Later layers can combine those patterns into more complex features, such as parts of a face. The network does not receive a hand-written rule for every useful shape. Still, people decide what data to use, how the layers connect, and how to measure success.
A basic training loop has five steps:
- Prepare examples and their target answers.
- Pass the input data forward through the network.
- Compare the prediction with the target answer.
- Send the error backward through the network.
- Update parameters and repeat the process.
Each pass helps the model adjust its predictions on the training examples. A model may appear accurate on those examples because it has learned their patterns, or even their quirks. That result does not prove the model will work just as well on new pictures.
Testing on held-out examples gives us a better view of how the model handles unfamiliar data. A model can still fail when those examples differ from real-world inputs. Test the model on examples it did not train on before trusting its apparent accuracy.
What Makes a Neural Network Deep?
“Deep” refers to the sequence of transformations between a model’s input and output, not to a guarantee of intelligence. A hidden layer is a processing stage between the input and the output. Multiple stages can form increasingly abstract representations of patterns.
There is no universally agreed layer count that separates shallow networks from deep ones. One common technical description calls a network deep when its credit-assignment path is greater than two. In plain terms, the model has several stages through which learning can affect earlier processing.
A first layer might respond to simple patterns, while later layers combine them into more complex ones. The value comes from representing patterns that matter to the task, not from adding layers for their own sake. A deeper network may offer greater representational capacity, but it can also add design and training demands.
Layer count is a design choice. We need to test whether a given depth fits the task and the available data. A simple problem may not need a complex network. A shallow model may be more suitable when the dataset is limited or the patterns are straightforward.
Even a network with many layers can perform poorly if its design does not fit the data. Depth alone does not make a model more accurate, useful, or easy to train. Choose depth for the patterns the task requires, not because a larger layer count sounds more advanced.
How Do Convolutional Neural Networks Process Images?
A CNN can learn visual features directly from pixels instead of requiring a person to specify every useful shape in advance. Convolutional neural networks are a common choice for computer vision because they process local visual patterns across an image.
Choose the vision task by the kind of output you need: a label, an object location, or a pixel-level map. A classification label can name an object, but it cannot show where that object appears. That difference changes which model task fits the job.
CNN filters learn visual patterns
A convolutional filter responds to a local pattern, such as an edge or a small shape. The network combines these responses across layers to learn more complex image features. A CNN learns those features from image data during training.
This design suits images because nearby pixels often form useful patterns together. A CNN can also be used for some text and time-series tasks, where local patterns matter. The best use depends on the data structure and the goal.
Classification, detection, and segmentation produce different outputs
Image classification assigns one or more labels to a whole image. Object detection returns labels and bounding boxes, which mark where objects appear. Semantic segmentation assigns a class label to each pixel.
| Task | Model output | Example input |
|---|---|---|
| Image classification | One or more image labels | Photo |
| Object detection | Object labels and bounding boxes | Street scene |
| Semantic segmentation | A class label for each pixel | Medical scan |
For example, a photo labeled “car” does not say where the car sits in the frame. A detection result can mark its location, while segmentation can map its pixels. Before choosing a vision model, decide whether the required result is a label, a location, or a pixel-level map.
How Do Recurrent Neural Networks and LSTMs Handle Sequences?
In a sentence, the meaning of a word can depend on the words that came before it. Recurrent neural networks process ordered data by passing information from one step to the next. Order matters in text, speech, and many time series.
An RNN carries a hidden state across sequence steps, while an LSTM is designed to learn longer-term dependencies. The hidden state holds information from earlier steps that may help process the current one.
RNNs carry information across a sequence
Imagine a model reading “The dog chased the ball.” It processes one word at a time, using earlier information as it reaches each new word. A recurrent neural network reuses the same basic processing across those steps.
In a time series, the input might be a set of measurements recorded in order. A value from earlier in the series can help the network interpret a later value. This makes recurrent neural networks useful for some sequence tasks.
LSTMs help retain longer-term dependencies
Long short-term memory networks, or LSTMs, are a type of RNN designed to learn which information may matter over longer sequences. Their internal structure helps preserve useful information across steps. They do not remember everything, and they can still miss important patterns.
The phrase “short-term memory” does not mean an LSTM stores a perfect record. The network learns from patterns in training data, and its performance depends on whether those patterns match the task. Modern sequence problems can use several architectures, so an LSTM is not automatically the best choice.
For a long sequence, check whether the model keeps the information the task needs rather than assuming that recurrence solves the memory problem.
Why Do Transformers Use Attention?
A Transformer can use attention to connect a word with other relevant words across the same input. Self-attention gives each sequence element a way to weigh information from other elements. It helps the model focus on useful relationships in text or other ordered data.
Attention helps process relationships across a sequence, but it does not make a model inherently factual or unbiased. A Transformer can relate words across an input without processing only one step at a time.
Self-attention connects relevant parts of a sequence
In “The bird landed because it was tired,” a model needs to connect “it” with the earlier subject. Self-attention can assign different weights to words that help represent that relationship. The model uses those connections as part of its processing.
Transformers are widely used in natural language processing, also called language processing. They can work with text and other sequences. Their ability to connect information across an input makes them useful for many language tasks.
Transformers underpin many language models
BERT and ChatGPT are examples associated with Transformer-based language models. ChatGPT is based on deep-learning language-model technology. That does not mean every detail of its current system is identical to one simple Transformer design.
Attention shows which parts of an input can influence other parts, but it does not prove that a response is true. A language model may produce smooth text while making a factual error. A fluent response from a Transformer still needs checking when accuracy matters.
What Are Generative Adversarial Networks Used For?
A GAN trains two networks together, with one generating examples and the other judging how they compare with real data. A generative adversarial network has a generator and a discriminator. The generator makes candidate examples, such as synthetic images.
GAN samples need validation before we treat them as realistic evidence. The discriminator learns to distinguish generated examples from real ones. Its feedback helps the generator produce examples that better match patterns in the training data.
The networks do not consciously compete. Their training goals create a back-and-forth process: the generator tries to make plausible examples, while the discriminator learns to spot generated ones. GANs can create synthetic data, though the output may still contain flaws.
Common uses include:
- Generating synthetic examples for experiments.
- Creating or transforming images.
- Supporting tests when real examples are scarce.
Synthetic data can help explore a problem, but it may not match real inputs in the ways that matter. A convincing image can still have errors or miss important details. Do not use a generated sample as ground truth until its quality and relevance have been checked.
How Does Deep Learning Differ From Machine Learning and AI?
AI is the umbrella, machine learning is one way to build AI systems, and deep learning is one family within machine learning. Deep learning is not a separate field outside AI. It is a specialized machine-learning approach based on multilayer neural networks.
Feature handling is one key difference between common workflows. Traditional machine-learning workflows often rely on people to select or design useful features. Deep learning can learn features from data, which may reduce manual feature engineering.
| Approach | Relationship to AI | Feature handling | Example use |
|---|---|---|---|
| Artificial intelligence | Broad field | Includes rule-based and learned systems | Planning |
| Traditional machine learning | AI subset | Often uses engineered features | Classification |
| Shallow neural network | Machine-learning model | Learns from input features | Prediction |
| Deep neural network | Machine-learning model with multiple layers | Learns hierarchical features | Image recognition |
Deep learning can reduce manual feature work, but it often needs more data and computing power. A simpler method may be easier to test and maintain. A model’s value depends on its task, its results, and its resource needs.
For a broader explanation of how systems learn from examples and make predictions, see how machine learning works. The right comparison is between methods that can solve the same problem.
Start with the simplest model that can meet the task’s accuracy and resource requirements.
Where Is Deep Learning Used?
A factory camera can help flag visible defects, while an EEG model analyzes a very different kind of signal. Deep learning applications range from computer vision to language processing and equipment analysis. Each model takes data as input and performs a defined task.
An application alone does not prove that a model suits every setting, especially when mistakes carry real costs. A vision system may inspect products, while a language model may classify text. The input and decision shape the design.
Vision and signal systems interpret images and measurements
Computer vision systems can inspect images or video. In manufacturing, visual inspection models can flag possible flaws on products. A person may still need to check the flagged item before a costly decision.
Speech and signal processing handle audio or measured signals. EEG analysis can support epilepsy diagnosis and seizure prediction. The model looks for patterns in brain-signal data; clinicians remain responsible for medical decisions.
Language models process and generate text
Natural language processing systems work with text. They can classify sentiment or translate between languages. Predictive maintenance models use equipment data to find patterns linked to possible faults.
| Application | Input | Example task |
|---|---|---|
| Computer vision | Images or video | Detect defects or recognize objects |
| Speech and signals | Audio or measured signals | Classify speech or EEG patterns |
| Natural language processing | Text | Classify sentiment or translate |
| Predictive maintenance | Equipment data | Identify patterns linked to faults |
The same type of model may behave differently across sites, devices, or groups of users. A factory camera may face lighting and product changes. EEG readings need context that an automated result cannot supply on its own.
Match the model to the decision it must support, and keep a human review where an incorrect result has serious consequences.
Should We Train From Scratch or Adapt a Pretrained Model?
A team with a new, specialized task can either train a model from the start or adapt a model that has already learned useful patterns. Training from scratch gives the team more control. Transfer learning often needs less labeled data and less training time.
The task’s similarity to earlier work helps determine which path fits. A pretrained model is a model fitted to earlier data. Transfer learning adapts that model to a new task.
Training from scratch suits tasks without a useful existing model
Starting from scratch means defining the task, gathering labeled examples, choosing an architecture, then training and evaluating the model. This route may take hours to weeks, depending on the task and computing resources. It can make sense when existing models do not fit the problem.
We also need a clear target for the model’s output. For example, a team might need categories that differ from those in common image datasets. Starting fresh gives room to shape the model around that need, but it also means learning useful patterns from the beginning.
Transfer learning reuses features for a new task
Transfer learning starts with a pretrained model such as SqueezeNet or GoogLeNet, then adapts it to new image classes. It usually needs less labeled data and less training time than training from scratch. The model’s earlier learning provides a starting point.
Pretrained layer activations can also serve as features for another model, such as an SVM. This approach uses the network to represent an input, then fits a separate classifier to those features.
Transfer learning is less useful when the earlier model’s data or task differs greatly from the new problem. Check that the pretrained model’s original task resembles your new one before investing in fine-tuning.
What Data and Computing Resources Do Models Need?
A large dataset helps only when its examples reflect the situations the model will face. Deep learning often benefits from plenty of good-quality training data, but quantity alone is not enough. Data must represent the real task and be prepared correctly.
Some training uses labeled examples, each paired with a known answer. Other methods can use unlabeled data. Synthetic examples may add variety, but they still need checks for quality and relevance.
Computing needs depend on the model and workload. GPUs can speed many deep-learning tasks because they handle parallel calculations well. Cloud computing and clusters can add capacity, but they do not promise a fixed training time.
A large dataset can still produce poor results if it omits important real-world conditions. A model trained on clear product images, for example, may face dim lighting in a factory. Data coverage matters as much as the total number of examples.
Before a project begins, check:
- Data coverage for expected conditions.
- Label quality and consistency.
- Available computing capacity.
- Deployment limits, such as memory and speed.
Deployment constraints shape what can run outside a lab. A large model may need more memory than a device can spare. Review rare but consequential cases before treating dataset size as a measure of readiness.
What Are the Limits of Deep Learning?
A model can make accurate predictions while leaving people unsure why it made them. Deep-learning models are often treated as black boxes because their internal decision process can be difficult to interpret. Strong test results do not establish fairness, robustness, or clear reasoning.
Performance can weaken when real inputs differ from the data used to train or test a model. This shift may come from new settings, changing users, or different equipment. A model that once worked well may not handle those changes reliably.
Complex predictions can be difficult to interpret
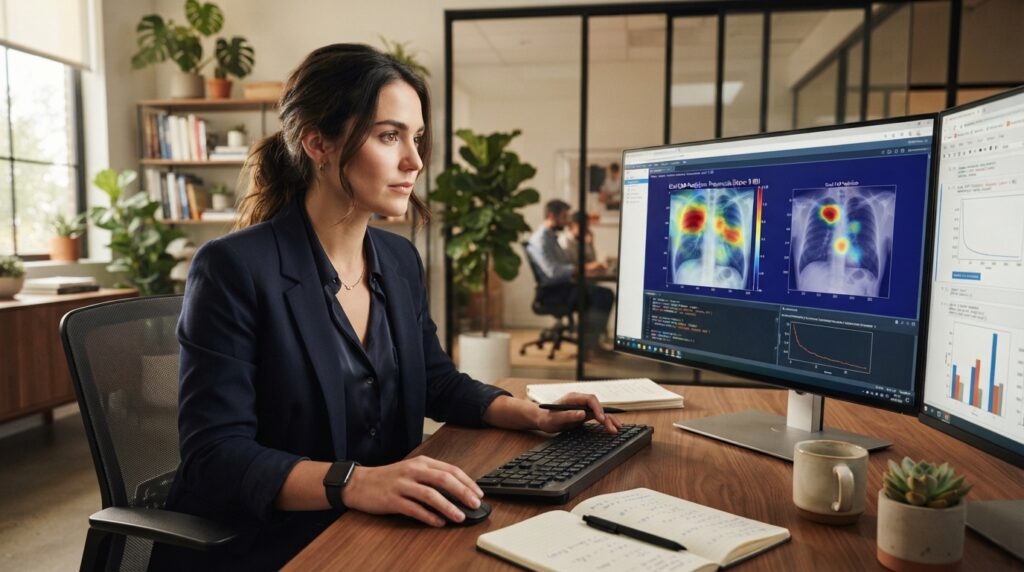
Grad-CAM and LIME can help inspect image-classification predictions. Grad-CAM highlights image regions that influenced a prediction. LIME examines how changes to parts of an input affect an output. These tools offer clues, not proof that a model is fully understandable.
A mathematical result published by Leshno, Lin, Pinkus, and Schocken in 1992 concerns approximation by multilayer feedforward networks with nonpolynomial activation functions. It describes a model’s ability to approximate functions under stated conditions. It does not promise accuracy on real-world data.
Data gaps and deployment constraints affect reliability
Quantization and pruning can reduce model size. Quantization uses fewer bits to represent values, while pruning removes parts of a network. Either change can affect output quality, so the modified model needs testing.
Three useful checks are:
- Evaluate cases that represent real use.
- Inspect errors and available explanations.
- Retest after deployment changes.
A strong score on one test set does not settle how a system behaves in every setting. Treat every explanation method as evidence to inspect, not proof that a model’s reasoning is fully transparent.
How Can We Start Learning Deep Learning?
A beginner can start with Python and linear algebra, then use a small coding project to connect the math to model behavior. Intermediate Python and basic linear algebra support the first steps. Prior machine-learning experience helps, but it is not required for the Deep Learning Specialization.
We also need enough machine-learning vocabulary to follow supervised training, where examples include known answers. A little practice with data and code makes new terms easier to understand. Start with small tasks rather than trying to learn every architecture at once.
Build the foundations before advanced architectures
Python helps us prepare data, run a model, and review its output. Linear algebra helps explain how networks combine numbers across layers. Basic concepts such as training examples, labels, and prediction errors give the math a clear purpose.
Practice with code and a structured course
Andrew Ng’s DeepLearning.AI Deep Learning Specialization has five courses. At five hours per week, its stated pace is about five weeks per course, except course three, estimated at about four weeks.
The first course takes four weeks and covers neural-network basics, shallow neural networks, and deep neural networks. Later topics include CNNs, RNNs, LSTMs, Transformers, computer vision, and natural language processing. A course can build knowledge, but it cannot by itself establish job readiness.
Dive into Deep Learning is an interactive book with math and executable Jupyter notebooks. It includes implementations using PyTorch, NumPy/MXNet, JAX, and TensorFlow. The framework release PyTorch 2.15, released October 28, 2026, is a dated software update, not a required beginner starting point.
Choose one learning path and complete its exercises before adding several courses at once.
What Do Deep Learning Jobs Pay, and What Do They Require?
In the United States, Glassdoor’s 2026 machine-learning engineer figure is a $168K median total pay, but specialized AI roles span different salary ranges. The machine-learning engineer total-pay range is $133K-$214K. Pay comparisons depend on role, seniority, and whether the figure covers salary or total pay.
These roles use different measures, so the table does not rank them from best to worst. Pay basis matters when we compare figures.
Salary ranges differ across AI and machine-learning roles
| Role | 2026 U.S. pay range | Pay basis |
|---|---|---|
| AI research scientist | $105,000-$170,000 | Salary range |
| AI product manager | $140,000-$195,000 | Salary range |
| LLM specialist | $125,000-$170,000 | Salary range |
| AI architect | $90,000-$180,000 | Salary range |
| Machine learning engineer | $133K-$214K | Total pay range |
Machine-learning engineer base pay is listed at $110K-$170K, with additional pay of $23K-$44K. The median total pay is $168K. Glassdoor’s 2026 machine-learning engineer pay figures use a total-pay measure.
Other listed salary ranges include $94,000-$137,000 for computer vision scientists and $105,000-$150,000 for machine-learning platform specialists. Big data specialists focused on AI infrastructure range from $130,000-$240,000. AI ethicists and compliance officers range from $60,000-$150,000.
AI architects range from $90,000-$180,000, while chief AI officers range from $200,000 to $500,000 or more. AI research scientists range from $105,000-$170,000. These figures describe different jobs, not one shared career ladder.
Seniority and specialization shape entry requirements
AI research scientist roles virtually require a PhD in computer science, mathematics, or a related field. LLM specialists need at least a bachelor’s degree, a master’s degree is preferred, and three to five years of natural language processing experience.
Computer vision scientists typically need three to five years of experience and a foundation in geometry, linear algebra, and physics. Chief AI officers typically need more than 15 years of experience, including at least five to seven years in senior AI leadership.
Compare pay figures on the same basis
“AI versus ML” is not a like-for-like pay category. Job title, seniority, total-pay versus salary-range basis, and role scope all affect a comparison. A credential can support an application, but it cannot guarantee a job.
Compare roles by responsibilities and compensation basis before treating two salary figures as a direct ranking.
Which Technology Jobs Are Growing as AI Spreads?
Employment projections can identify occupations expected to grow, but they cannot promise that any job is immune to automation or industry change. Data scientists are projected to grow 33.5% from 2024 to 2034 in the United States. That projection describes expected employment change, not a guarantee about an individual job.
Information security analysts, actuaries, operations research analysts, and computer and information research scientists are each projected to grow by at least 19.0% during that period. These five occupations, including data scientists, are projected growth areas, not assured paths to lasting employment.
Software developer employment is projected to grow 15.8% from 2024 to 2034, adding more than 267,000 jobs. That is the largest numerical increase among the occupations in this comparison. A percentage rate and a job count describe different kinds of change.
U.S. employment projections for data scientists show the 33.5% growth estimate from 2024 to 2034. The number reflects a forecast for the occupation as a whole, not a promise to any one worker.
Some listed occupations are projected to decline from 2024 to 2034: procurement clerks; credit authorizers, checkers, and clerks; legal secretaries and administrative assistants; and customer service representatives. These projections do not establish AI as the sole cause of decline. Industry needs and other changes can also shape employment.
Use projected growth as one career-planning signal alongside your skills, interests, and the work employers actually need.
Growth estimates cannot show whether a specific role will change, shrink, or gain new duties. Use projected growth as one career-planning signal alongside your skills, interests, and the work employers actually need.
Conclusion
Deep learning is most useful when we understand both the pattern a model can learn and the cases it may miss. Layered models learn from data, but their results depend on choosing a suitable task, useful examples, and an appropriate level of trust.
We can begin with a small image classifier and examine errors on pictures it has not seen. That exercise makes model behavior concrete and gives us a chance to question weak predictions. Start with one small dataset, train a simple model, and inspect its mistakes before scaling the project.